Linear Algebra
LU decomposition
Factor a matrix into lower and upper triangular matrices to solve linear systems efficiently.
Definition
LU splits the coefficients of a linear system into two matrices whose equations can be solved one at a time. In $Ax=b$, $x$ is the vector (a column of numbers) containing the unknowns, $b$ is the given right-hand side, and $A$ stores the numbers multiplying the unknowns. The notation $A\in\mathbb R^{n\times n}$ means a square matrix with $n$ rows, $n$ columns, and real-number entries.
The main diagonal runs from top left to bottom right. A lower triangular matrix has zeros above it; an upper triangular matrix has zeros below it. Unit lower triangular additionally means diagonal entries all equal to $1$. An LU decomposition is
\[A=LU,\qquad \underbrace{\begin{bmatrix}2&1\\4&3\end{bmatrix}}_{A} =\underbrace{\begin{bmatrix}1&0\\2&1\end{bmatrix}}_{L} \underbrace{\begin{bmatrix}2&1\\0&1\end{bmatrix}}_{U}.\]Notice the zeros in opposite halves of $L$ and $U$. We will derive this example below. See LAPACK’s LU definition. The matrix-decomposition overview explains matrix multiplication, transpose $A^T$ (exchanging rows and columns), and other prerequisite notation.
When the factorization exists
The identity $I$ has diagonal entries $1$ and other entries $0$, so $Ix=x$. An inverse $A^{-1}$ undoes $A$, satisfying $A^{-1}A=AA^{-1}=I$. A square matrix with an inverse is nonsingular; without one, it is singular. For example, $\operatorname{diag}(2,0)$, meaning a diagonal matrix with entries $2$ and $0$, loses the second coordinate and cannot be undone. See OpenStax’s inverse matrices.
The determinant, written $\det A$, is a number associated with a square matrix; it is nonzero exactly when the matrix is nonsingular. For a $2\times2$ matrix,
\[\det\begin{bmatrix}a&b\\c&d\end{bmatrix}=ad-bc.\]Our example has determinant $2\cdot3-1\cdot4=2$, so it is nonsingular. See OpenStax’s determinant examples.
A leading principal submatrix is the square block in the upper-left corner. The notation $A_{1:k,1:k}$ selects the first $k$ rows and columns, and its determinant is a leading principal minor. In our example the $1\times1$ block has determinant $2$, and the full $2\times2$ block also has determinant $2$. Both are nonzero. These checks matter because elimination without row exchanges must be able to proceed through each initial block.
For a nonsingular matrix, the unit-lower-triangular LU factorization exists and is unique if every leading principal minor is nonzero. See ALAFF, Theorem 5.2.3.4:
\[\det(A_{1:k,1:k})\ne0,\qquad k=1,2,\ldots,n.\]If row exchanges are required, we instead use $PA=LU$. A permutation matrix $P$ is an identity matrix with reordered rows; multiplication by it performs the same row reordering. For example,
\[\begin{bmatrix}0&1\\1&0\end{bmatrix} \begin{bmatrix}a&b\\c&d\end{bmatrix} =\begin{bmatrix}c&d\\a&b\end{bmatrix}.\]This row-exchange version is explained in ALAFF’s pivoted LU algorithm. The applications below assume that $A$ is nonsingular and admits the factorization $A=LU$ without row exchanges; for $PA=LU$, replace the right-hand side $b$ by $Pb$.
Intuition: elimination with a memory
Gaussian elimination subtracts multiples of earlier equations from later ones to remove unknowns. The pivot is the coefficient we divide by to choose such a multiple; the multiplier is how many copies of that row we subtract. For example, to remove a $4$ beneath a pivot $2$, subtract $4/2=2$ copies of the pivot row. LU keeps both the final rows and these multipliers. $U$ is the simplified system; $L$ remembers how to rebuild the original rows.
For example,
\[A=\begin{bmatrix}2&1\\4&3\end{bmatrix}.\]Subtract twice row 1 from row 2. The new second row is $(0,1)$, so
\[U=\begin{bmatrix}2&1\\0&1\end{bmatrix},\qquad L=\begin{bmatrix}1&0\\2&1\end{bmatrix}.\]The $2$ in $L$ remembers the subtraction multiplier. Multiplication by $L$ reverses the subtraction: the original second row equals twice the first row of $U$ plus its second row. Thus $LU=A$. Elimination and reconstruction have opposite signs; the stored multiplier is $+2$, even though the elimination operation subtracts $2$ times a row.
A three-variable example
Consider
\[A=\begin{bmatrix}2&1&1\\4&3&3\\8&7&9\end{bmatrix}.\]The symbol $R_i$ means row $i$, and $\leftarrow$ means “replace with.” Use the first pivot, $2$, to remove the entries below it. The multipliers are $4/2=2$ and $8/2=4$:
\[R_2\leftarrow R_2-2R_1,\qquad R_3\leftarrow R_3-4R_1.\]This leaves rows $(0,1,1)$ and $(0,3,5)$. Now subtract $3$ times the new second row from the new third row. The result is $(0,0,2)$. Therefore
\[U=\begin{bmatrix}2&1&1\\0&1&1\\0&0&2\end{bmatrix},\qquad L=\begin{bmatrix}1&0&0\\2&1&0\\4&3&1\end{bmatrix}.\]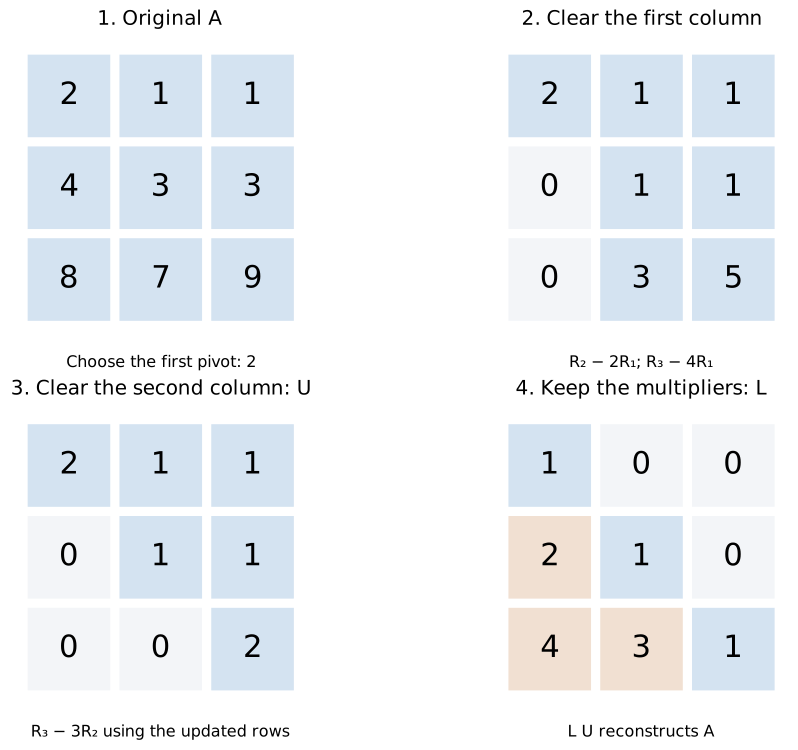
The second multiplier uses the updated third-row entry, $3$, rather than the original entry $7$. That is why the lower factor stores $l_{32}=3$. To check the record, reconstruct the original third row as
\[4(2,1,1)+3(0,1,1)+(0,0,2)=(8,7,9).\]What a pivot means and why row exchanges help
A pivot is the coefficient used to eliminate the entries below it. If it is zero, the required division is impossible. This does not necessarily mean the whole matrix is singular:
\[A=\begin{bmatrix}0&1\\1&1\end{bmatrix},\qquad \det A=-1.\]Swap the rows with \(P=\begin{pmatrix}0&1\\1&0\end{pmatrix}\). Then
\[PA=\begin{bmatrix}1&1\\0&1\end{bmatrix}=IU.\]Here $L=I$, and elimination can proceed. Reordering equations preserves their solution, provided we also reorder $b$ to $Pb$.
A nonzero pivot can also be too small for comfortable numerical computation. In \(\begin{pmatrix}\varepsilon&1\\1&1\end{pmatrix}\), the first multiplier is $1/\varepsilon$. For $\varepsilon=10^{-4}$ it is $10^4$, creating large intermediate quantities. The magnitude of a real number is its absolute value: both $-5$ and $5$ have magnitude $5$. Partial pivoting chooses the largest-magnitude entry in the remaining part of the current column, swaps its row into place, and thereby bounds the elimination multipliers by $1$ in magnitude in exact arithmetic, meaning calculations without rounding. Computers instead use floating-point arithmetic, representing numbers with limited precision; for example, storing $1/3$ as $0.3333$ introduces a rounding error. Large intermediate values can magnify such errors. Partial pivoting does not guarantee that every intermediate entry stays small. See ALAFF’s partial-pivoting algorithm.
The leading-principal-minor condition in the definition says that, for nonsingular $A$, every initial block permits the next unpivoted step. Row pivoting supplies a different order when that sequence is blocked.
Usages
1. Solving linear systems
Let’s say we have a linear system
\[Ax = b\]to solve. If we perform $LU$ decomposition, we get:
\[Ax = LUx = b\]If we write:
\[Ux = y\]then the linear system could be rewritten into:
\[Ax = LUx = L(Ux) = Ly = b\]Forward substitution solves $Ly=b$ from the first row downward. Backward substitution solves $Ux=y$ from the last row upward. Each new equation has only one unknown left after the previously computed values are substituted.
For the three-variable example above, take $b=(4,10,24)^T$. The lower triangular solve gives
\[y_1=4,\qquad y_2=10-2y_1=2,\qquad y_3=24-4y_1-3y_2=2.\]The upper triangular solve then gives
\[x_3=y_3/2=1,\qquad x_2=y_2-x_3=1,\qquad x_1=(y_1-x_2-x_3)/2=1.\]Direct substitution verifies $A(1,1,1)^T=b$. The dependency direction is the reason for the names forward and backward, not an arbitrary convention.
The factorization does most of the work. Once it exists, another right-hand side needs only the two substitution passes. This distinction matters for both hand calculation and software. See LAPACK’s factor-and-solve workflow.
A dense matrix is stored and processed as a full array, rather than exploiting a pattern of many zeros. A flop is one floating-point arithmetic operation, such as an addition or multiplication. The notation $O(n^2)$ describes work bounded by a constant times $n^2$ for sufficiently large $n$; it describes growth, rather than an exact operation count. For conventional dense $LU$ factorization, the floating-point operation count is $\frac{2}{3}n^3 + O(n^2)$ flops, counting each multiplication and addition separately. Thus $\frac{2}{3}n^3$ is the leading term, rather than an exact count. Forward and backward substitution together cost $O(n^2)$ per right-hand side. Once $L$ and $U$ have been computed, they can be reused to solve systems with the same $A$ and different right-hand sides without repeating the factorization.
2. Computing determinants
\[\det A = \det L\cdot\det U=\prod_{i=1}^n u_{ii},\]because unit lower triangular $L$ has determinant $1$, and a triangular matrix’s determinant is the product of its diagonal entries. For our three-variable example, $\det A=2\cdot1\cdot2=4$. With pivoted $PA=LU$, include the permutation sign: $\det A=\det(P)\prod_i u_{ii}$. Each row swap contributes a factor $-1$.
3. Matrix inversion
Inversion is basically solving
\[AX = I\]Each column of $I$ supplies a different right-hand side, so the same factors solve all $n$ systems. Their solutions form the columns of $A^{-1}$. If the goal is only one solution $x$, the two triangular solves already produce it; computing the entire inverse adds work that the solve does not need.
History
Introduction of $A = g’h$
$LU$ decomposition is relatively modern concept compared to other crucial matrix operations such as Gaussian elimination where it’s name hints its history. The first appearance of decomposing a matrix into two triangular matrices in a journal is from a paper in 1938 by Polish mathematician and professor of astronomy at Jagiellonian University at Kraków, Poland, Tadeusz Banachiewicz, known as “Méthode de résolution numérique des équations linéaires, du calcul des déterminants et des inverses, et de réduction des formes quadratiques”, translated as “Method for the Numerical Solution of Linear Equations, Calculation of Determinants and Inverses, and Reduction of Quadratic Forms”.
The reason why he introduced this is to make numerical calculations simpler and less error-prone, especially in his field: astronomy and geodesy, the measurement of Earth’s shape and positions on its surface. As an astronomer, Banachiewicz realised that astronomers often had to solve linear systems arising from orbital calculations, observation data, and least-squares estimation: fitting predictions to measurements by minimizing the sum of squared discrepancies. The normal-equations section below works through this idea. At the time, there were no LLMs, super fast calculator apps, nor Casio calculators. What they had were mechanical calculators.
To solve this problem, Banachiewicz came up with “Cracovian Algebra” which is about organizing matrix calculations, where the centre of its idea was about organizing matrix calculations column-wise which was more convenient for mechanical calculators to work on.
While working on his algebra, he discovered that often times, when we perform Gaussian eliminations, we often get two different information: the resulting matrix of the elimination, and the multipliers used for the elimination. For example,
\[A = \begin{bmatrix} 2 & 1\\ 4 & 3 \end{bmatrix}\]If we perform eliminations, we get:
\[U = \begin{bmatrix} 2 & 1\\ 0 & 1 \end{bmatrix}\]by multipling the first row by $2$, and subtracting it two the second row. We could actually store that information in a separate matrix:
\[L = \begin{bmatrix} 1 & 0\\ 2 & 1 \end{bmatrix}\]obtaining
\[A = LU\]In his paper, he states that:
§ 1. Considérons le système de $n$ équations linéaires à $n$ inconnues
\[\begin{aligned} A_{11}x_1 + A_{21}x_2 + \ldots + A_{n1}x_n + A_{n+1,1} &= 0 \\ A_{12}x_1 + A_{22}x_2 + \ldots + A_{n2}x_n + A_{n+1,2} &= 0 \\ &\vdots \\ A_{1n}x_1 + A_{2n}x_2 + \ldots + A_{nn}x_n + A_{n+1,n} &= 0 \end{aligned} \qquad (1.1)\]ayant une solution unique.
En posant
\[\mathrm{X} = 1\{x_1\ \ x_2\ \ldots\ x_n\ \ 1\} \qquad (1.\mathrm{A})\] \[\mathrm{A}' = \begin{vmatrix} A_{11} & A_{21} & \ldots & A_{n1} & A_{n+1,1} \\ A_{12} & A_{22} & \ldots & A_{n2} & A_{n+1,2} \\ \vdots & \vdots & & \vdots & \vdots \\ A_{1n} & A_{2n} & \ldots & A_{nn} & A_{n+1,n} \end{vmatrix} \qquad (1.\mathrm{B})\]nous écrirons le système (1.1), comme d’ordinaire,
\[\mathrm{X}\cdot 1\mathrm{A}' = 0 \qquad (1.1\text{-bis})\]Supposons maintenant $\mathrm{A}’$ décomposé en un produit de deux cracoviens $\mathrm{g}’$ et $\mathrm{h}$ tels que
\[\mathrm{g}' = \begin{vmatrix} 1 & g_{21} & g_{31} & \ldots & g_{n1} & g_{n+1,1} \\ 0 & 1 & g_{32} & \ldots & g_{n2} & g_{n+1,2} \\ 0 & 0 & 1 & \ldots & g_{n3} & g_{n+1,3} \\ \vdots & \vdots & \vdots & & \vdots & \vdots \\ 0 & 0 & 0 & \ldots & 1 & g_{n+1,n} \end{vmatrix} \qquad \mathrm{h} = \begin{vmatrix} h_{11} & h_{21} & h_{31} & \ldots & h_{n1} \\ 0 & h_{22} & h_{32} & \ldots & h_{n2} \\ 0 & 0 & h_{33} & \ldots & h_{n3} \\ \vdots & \vdots & \vdots & & \vdots \\ 0 & 0 & 0 & \ldots & h_{nn} \end{vmatrix} \qquad (1.\mathrm{C})\]que nous appellerons facteurs canoniques de $\mathrm{A}’$. On suppose les équations (1.1) disposés de façon que $h_{ii} \neq 0$ ($i = 1, 2, \ldots n$); ceci est toujours possible, car dans le cas contraire le déterminant du système (1.1) serait égal à zéro.
Avec
\[\mathrm{A}' = \mathrm{g}'\cdot\mathrm{h} \qquad (1.2)\]l’équation (1.1-bis) donne
\[\mathrm{X}\cdot 1(\mathrm{g}'\cdot\mathrm{h}) = \mathrm{X}\cdot(\mathrm{h}\cdot\mathrm{g}') = \mathrm{X}\cdot 1\mathrm{g}'\cdot\mathrm{h} = 0, \qquad (1.1\text{-ter})\]
Now if we translate this original text to English using LLMs, we get:
§ 1. Consider the system of $n$ linear equations in $n$ unknowns
\[\begin{aligned} A_{11}x_1 + A_{21}x_2 + \ldots + A_{n1}x_n + A_{n+1,1} &= 0 \\ A_{12}x_1 + A_{22}x_2 + \ldots + A_{n2}x_n + A_{n+1,2} &= 0 \\ &\vdots \\ A_{1n}x_1 + A_{2n}x_2 + \ldots + A_{nn}x_n + A_{n+1,n} &= 0 \end{aligned} \qquad (1.1)\]having a unique solution.
Setting
\[\mathrm{X} = 1\{x_1\ \ x_2\ \ldots\ x_n\ \ 1\} \qquad (1.\mathrm{A})\] \[\mathrm{A}' = \begin{vmatrix} A_{11} & A_{21} & \ldots & A_{n1} & A_{n+1,1} \\ A_{12} & A_{22} & \ldots & A_{n2} & A_{n+1,2} \\ \vdots & \vdots & & \vdots & \vdots \\ A_{1n} & A_{2n} & \ldots & A_{nn} & A_{n+1,n} \end{vmatrix} \qquad (1.\mathrm{B})\]we shall write the system (1.1), as usual,
\[\mathrm{X}\cdot 1\mathrm{A}' = 0 \qquad (1.1\text{-bis})\]Suppose now that $\mathrm{A}’$ is decomposed into a product of two cracovians $\mathrm{g}’$ and $\mathrm{h}$ such that
\[\mathrm{g}' = \begin{vmatrix} 1 & g_{21} & g_{31} & \ldots & g_{n1} & g_{n+1,1} \\ 0 & 1 & g_{32} & \ldots & g_{n2} & g_{n+1,2} \\ 0 & 0 & 1 & \ldots & g_{n3} & g_{n+1,3} \\ \vdots & \vdots & \vdots & & \vdots & \vdots \\ 0 & 0 & 0 & \ldots & 1 & g_{n+1,n} \end{vmatrix} \qquad \mathrm{h} = \begin{vmatrix} h_{11} & h_{21} & h_{31} & \ldots & h_{n1} \\ 0 & h_{22} & h_{32} & \ldots & h_{n2} \\ 0 & 0 & h_{33} & \ldots & h_{n3} \\ \vdots & \vdots & \vdots & & \vdots \\ 0 & 0 & 0 & \ldots & h_{nn} \end{vmatrix} \qquad (1.\mathrm{C})\]which we shall call the canonical factors of $\mathrm{A}’$. The equations (1.1) are assumed arranged so that $h_{ii} \neq 0$ ($i = 1, 2, \ldots n$); this is always possible, for otherwise the determinant of the system (1.1) would be equal to zero.
With
\[\mathrm{A}' = \mathrm{g}'\cdot\mathrm{h} \qquad (1.2)\]equation (1.1-bis) gives
\[\mathrm{X}\cdot 1(\mathrm{g}'\cdot\mathrm{h}) = \mathrm{X}\cdot(\mathrm{h}\cdot\mathrm{g}') = \mathrm{X}\cdot 1\mathrm{g}'\cdot\mathrm{h} = 0, \qquad (1.1\text{-ter})\]
Reading the original notation
In the displayed formulas, $\mathrm{A}’$ and $\mathrm{g}’$ are augmented arrays: each has an extra column for the constant terms. Their primes should not be read as modern transpose symbols. Banachiewicz instead uses the prefix $1$ for the transposing cracovian, whose displayed array is an identity matrix. The first index in his entries denotes the column, and the second denotes the row; for example, $A_{21}$ is in the first row and second column. These conventions can be seen in §1, equations (1.A)–(1.C), of the original paper, pp. 393–394.
The dot also has a special meaning. To distinguish it from ordinary matrix multiplication, write the cracovian product as $R \circ S$. If $R$ and $S$ denote the arrays as displayed, then
\[R \circ S = S^T R, \qquad (R \circ S)_{ij} = \sum_k S_{ki}R_{kj}.\]A dot product multiplies matching coordinates and adds: $(1,2)^T!\cdot(3,4)^T=1\cdot3+2\cdot4=11$. Each output entry above is a dot product of a column of $S$ with a column of $R$, so the two input arrays (the operands) must have the same number of rows. Consequently,
\[R \circ I = R, \qquad I \circ R = R^T.\]This explains why the original prefix $1$ transposes an array even though ordinary left multiplication by an identity matrix would leave it unchanged. Unlike ordinary matrix multiplication, changing parentheses can change a cracovian product: $(R\circ S)\circ T$ need not equal $R\circ(S\circ T)$. This property is called nonassociativity; a sequence of products is evaluated from left to right. These product and transposition rules are also given in Kociński, §3, definitions 3.1–3.3 and 3.5.
Translating the equations into modern matrix algebra
Let $C$ denote the coefficient matrix as displayed in (1.B), and let $c$ be its final column. In modern notation,
\[C_{ij} = A_{ji}, \qquad c_i = A_{n+1,i}, \qquad \mathcal A = [\,C\mid c\,], \qquad \widehat x = \begin{bmatrix}x\\1\end{bmatrix}.\]The original $\mathrm X = 1{x_1\ \cdots\ x_n\ 1}$ is the column $\widehat x$. Thus $\mathrm X\cdot 1\mathrm A’ = 0$ translates to
\[\widehat x \circ \mathcal A^T = \mathcal A\widehat x = Cx + c = 0.\]This is the usual system $Cx = b$ with $c = -b$: the appended column contains the negative of the modern right-hand side.
Next, let $\mathcal G = [\,G\mid q\,]$ and $H$ denote the displayed arrays $\mathrm g’$ and $\mathrm h$. Here $G$ is unit upper triangular and $H$ is upper triangular with nonzero diagonal entries. Equation (1.2) translates to
\[\mathcal A = \mathcal G \circ H = H^T\mathcal G, \qquad C = H^TG, \qquad c = H^Tq.\]The dimensions now agree: $H^T$ is $n\times n$ and $\mathcal G$ is $n\times(n+1)$. The coefficient matrix is a product of a lower triangular matrix $H^T$ and a unit upper triangular matrix $G$.
The manipulation in (1.1-ter) has the same meaning as the ordinary matrix identity
\[\mathcal A\widehat x = H^T(\mathcal G\widehat x) = 0.\]Since $H^T$ is invertible, this gives $\mathcal G\widehat x = Gx + q = 0$, corresponding to the original equation (1.3). Equivalently, set $y = -q$, solve $H^Ty = b$ by forward substitution, and then solve $Gx = y$ by backward substitution.
To obtain the unit-lower-triangular convention used earlier in this article, define
\[D = \operatorname{diag}(h_{11},\ldots,h_{nn}), \qquad L = H^TD^{-1}, \qquad U = DG.\]Then $L$ has diagonal entries $1$, $U$ is upper triangular, and $LU = H^TG = C$. For the earlier example,
\[H = \begin{bmatrix}2&4\\0&1\end{bmatrix}, \qquad G = \begin{bmatrix}1&\tfrac12\\0&1\end{bmatrix}, \qquad D = \begin{bmatrix}2&0\\0&1\end{bmatrix},\]which gives exactly \(L = \begin{bmatrix}1&0\\2&1\end{bmatrix}\) and \(U = \begin{bmatrix}2&1\\0&1\end{bmatrix}\). Banachiewicz’s factorization therefore becomes modern $LU$ after translating the product and choosing the diagonal normalization.
The claim here is that by using this calculation based on his algebra, we have less mathematical quantities, not number of operations, than the traditional elimination process.
D’autre part la commodité de la forme cracovienne des équations (2.3) et (2.4) facilite beaucoup les calculs.
which translates into
On the other hand, the convenience of the Cracovian form of equations (2.3) and (2.4) greatly facilitates the calculations.
At that time, the speed of calculations wasn’t the main issue, but the intermediate quantities that arises from the calculations.
Solving normal equations
This section derives the equations characterizing a least-squares fit. QR factorization obtains the same fit through orthonormal coordinates and a triangular solve, avoiding explicit formation of $A^TA$. Gram–Schmidt explains how those coordinates are constructed.
Least squares chooses unknowns to minimize the sum of squared discrepancies between predictions and measurements. The normal equations are the linear equations that characterize this best fit; they apply whether the original system has an exact solution or only an approximate fit. See LAPACK’s least-squares formulation.
For later use, linearly independent columns means no column can be made by multiplying the others by numbers and adding. Rank counts the largest number of independent columns. Full column rank means all columns are independent: for example, $(1,0)^T$ and $(0,1)^T$ are, but $(1,0)^T$ and $(2,0)^T$ are not. Their combinations form the column space: all predictions $Ax$ the model can make. See the overview’s rank examples before the general derivation below.
This was important for astronomers, surveyors, and geodesists, because they had to estimate unknown quantities from measurements containing errors.
For example, imagine you are an astronomer, and you are trying to estimate a position of a star. You measure its $x$ position three times, and you get:
\[\begin{aligned} x = 2.0\\ x = 2.2\\ x = 1.9 \end{aligned}\]So what should be the position of that star? Average them?
The approach astronomers took was to choose the value $x$ that minimizes the total squared measurement error:
\[\min_x [(x - 2.0)^2 + (x - 2.2)^2 + (x - 1.9)^2]\]The quantity inside the brackets is an objective function: a number measuring how bad a proposed $x$ is. It is a quadratic function, whose graph is an upward-opening parabola. A derivative measures its slope. At the bottom the slope is zero; for example, $(x-2)^2$ has derivative $2(x-2)$, which vanishes at $x=2$. Applying the same rule to the three squared errors gives:
\[2(x - 2.0) + 2(x - 2.2) + 2(x - 1.9) = 0\]and we get
\[\begin{aligned} 3x &= 6.1 \\ x &= \frac{6.1}{3} \approx 2.0333 \end{aligned}\]Differentiating this sum of squared errors turns the minimization problem into a linear equation. With several unknowns it becomes a linear system. This was the reason why solving linear systems were very important.
To generalize, let $A\in\mathbb R^{m\times n}$ describe $m$ measurements and $n$ unknowns, let $b\in\mathbb R^m$ contain the measurements, and let $x\in\mathbb R^n$ contain the unknowns. The residual vector $r=b-Ax$ lists the discrepancies left after fitting. The 2-norm $\lVert r\rVert_2$ is its ordinary length, so $\lVert r\rVert_2^2=r_1^2+\cdots+r_m^2$. For example, $r=(3,4)^T$ has length $5$ and squared length $25$. See vector norms for why this notation represents the total squared error.
Using this notation, the least-squares problem is
\[\min_x \lVert Ax - b \rVert_2^2.\]The squared 2-norm gives:
\[\begin{aligned} F(x) &= (Ax - b)^T(Ax - b) \\ &= x^TA^TAx - 2b^TAx + b^Tb \end{aligned}\]A matrix is symmetric when it equals its transpose. A quadratic form combines squared coordinates and products of coordinate pairs; for example, $2x_1^2+2x_1x_2+3x_2^2$. The term $x^TA^TAx$ is a quadratic form with symmetric matrix $A^TA$. Its derivative is $2A^TAx$; the linear and constant terms supply the remaining contributions.
With several unknowns, we collect one derivative for each coordinate into the gradient, written $\nabla F$. For example, $F(x_1,x_2)=x_1^2+3x_2^2$ has gradient $(2x_1,6x_2)^T$. Each component measures the slope when just that coordinate changes. For our least-squares objective, this gives:
\[\nabla F(x) = 2A^TAx -2A^Tb\]A point where every component of the gradient vanishes is a stationary point. To find it, solve
\[\nabla F(x) = 0\]thus
\[\begin{aligned} 2A^TAx - 2A^Tb &= 0\\ 2A^TAx &= 2A^Tb \\ \therefore A^TAx &= A^Tb \end{aligned}\]which is called the normal equation.
A sum of squared linear discrepancies is a convex quadratic: along any straight line in the unknowns, its graph is an upward-opening parabola or a constant. Thus a stationary point is a global minimum, rather than a hilltop. For example, $(x_1+x_2-1)^2$ is minimized by every pair with $x_1+x_2=1$; the bottom can be flat in some directions. See Convexity for the general local-to-global proof and its distinction from uniqueness.
A symmetric matrix $H$ is positive definite if $z^THz>0$ for every nonzero $z$; positive semidefinite requires $z^THz\ge0$ and allows equality for nonzero $z$. The abbreviation SPD means symmetric positive definite. Here $H=A^TA$ and $z^THz=\lVert Az\rVert_2^2$. Full column rank makes this strictly positive for nonzero $z$, so the minimizing $x$ is unique. If columns are dependent, some nonzero $z$ satisfies $Az=0$; adding it to a minimizer changes $x$ without changing the predictions $Ax$. Then $A^TA$ is singular and positive semidefinite, and $x$ is not unique, although $Ax$ is. See positive-definite and semidefinite matrices and LAPACK’s least-squares conditions.
The reason this is called a normal equation is because if we rearrange the equation, we get:
\[A^T(b - Ax) = 0\]where we can use the residual vector $r$:
\[A^Tr = 0\]Perpendicular, or orthogonal, means the dot product is zero. Each entry of $A^Tr$ is the dot product of a column of $A$ with $r$, so the equation says that the residual is perpendicular to every model direction. For a simpler constant-fit example, measurements $(1,2,6)^T$ give $x=3$ and $r=(-2,-1,3)^T$; its dot product with the model column $(1,1,1)^T$ is $-2-1+3=0$.
An orthogonal projection is the closest vector in the allowed column space to $b$; here it is the prediction $Ax$. The remaining discrepancy points perpendicular to that space. In geometry, normal means perpendicular, which explains the name normal equations. See MIT’s least-squares and projection explanation.
This is where the 1944 paper “An Attempt at a Systematic Classification of Some Methods for the Solution of Normal Equations” by Danish geodesist Henry Jensen comes in. This paper was to bridge the mathematical relationship between the conventional Gaussian elimination, Banachiewicz’s Cracovian method, and Cholesky’s method.
A row subtraction can itself be represented by a matrix. For our two-row example,
\[E=\begin{bmatrix}1&0\\-2&1\end{bmatrix},\qquad EA=U.\]Such a matrix is called an elimination matrix. With several row operations, call them $E_1,E_2,\ldots,E_k$ in their order of application. Gaussian elimination without row exchanges becomes
\[E_k\cdots E_2E_1A = U\]Banachiewicz’s method was
\[A = g'h\]and Cholesky’s method was
\[A = LL^T\]for a special kind of matrix, the symmetric positive-definite matrix $A$.
For the Gaussian-elimination factorization without row exchanges, $L=(E_k\cdots E_2E_1)^{-1}$: it undoes those row operations. This $L$ need not be the same as the lower factor in the Cholesky formula.
The reason he used triangular factorization was to show the close relationship between these methods.
The next paper actually tackles solving numerical equations. This is another 1944 paper “A Matrix Presentation of Least Squares and Correlation Theory with Matrix Justification of Improved Methods of Solution” by an American statistician and an associate professor of mathematics at the University of Michigan, Paul S. Dwyer.
Statistics also deal with measured data, so often times, they had to deal with normal equations. Dwyer’s question was to find the systematic process of solving normal equations in matrix algebra.
He first showed that Doolittle algorithm, an algorithm used to solve linear systems using Gaussian elimination systematically, can be represented as a product of two matrices:
\[A = S'T\]Here $A$ denotes the coefficient matrix of the normal equations, rather than the original measurement matrix. It is a Gram matrix: its entries are pairwise dot products of the measurement matrix’s columns. For example, columns $(1,0)^T$ and $(1,1)^T$ give the Gram matrix
\[\begin{bmatrix}1&1\\1&2\end{bmatrix},\]because their squared lengths are $1$ and $2$ and their mutual dot product is $1$. Writing the measurement matrix as $B$ avoids the repeated symbol: the Gram matrix is $B^TB$. See quadratic forms and Gram matrices. Here, $S’$ is the lower triangular, and $T$ is the upper triangular.
He continues to show useful properties of this factorization:
7. A more general theory––solution of matrix equations by factorization. … The key formula in this development is $A - S’T = 0$ and all subsequent formulas stem from this. Hence if $A$ can be factored into any matrices, $S’$ and $T$, not necessarily triangular, the results of section 6 follow. …
In this normal-equation setting, the coefficient matrix is a Gram matrix $A = B^TB$. Such a matrix is always symmetric positive semidefinite, since $z^TAz = \lVert Bz\rVert_2^2 \geq 0$. It is positive definite only if $B$ has full column rank. Thus the nonsingular normal-equation case gives an SPD matrix; the Gram-matrix form alone does not guarantee positive definiteness.
Numerical introduction
Before the historical discussion, separate two sources of error. Conditioning describes sensitivity in the problem itself. For example, $A=\operatorname{diag}(1,0.001)$ turns $b=(1,0)^T$ into $x=(1,0)^T$, but changing only the second entry of $b$ to $0.001$ changes the solution to $(1,1)^T$. A small input change produces a much larger output change. A condition number measures such sensitivity; matrix norms explains how to quantify it.
Numerical stability describes the algorithm’s behavior under rounding. Backward error asks how much the original data would need to change for the computed answer to be an exact solution. A stable solver aims for a small backward error, but a sensitive problem can still have a large error in the answer. This distinction is developed in LAPACK’s error bounds.
In 1947, there comes a new paper called “Numerical Inverting of Matrices of High Order”, written by the famous Hungarian-American polymath and a professor at the Institute of Advanced Study(IAS) at Princeton, NJ, John von Neumann, and an American mathematican and Associate Project Director of the Electronic Computer Project at IAS, Herman Heide Goldstine.
IAS at the time was designing a computer called the “IAS Machine” that would replace and outperform ENIAC. As computers are being utilised in the mathematics world, it has become important to guarantee numerical stability of solving linear systems in computers.
Computers store numbers with finite precision, so many real numbers cannot be represented exactly and calculations introduce rounding errors. In 1943, an American mathematician and a professor at Columbia University, Harold Hotelling, published a paper “Some New Methods in Matrix Calculation” where he derived the upper bound of rounding errors of Doolittle method in computers, suggesting that “The rapidity with which this(the upper bound) increases with $p$ is a caution against relying on the results of the Doolittle method or other similar elimination methods with any moderate numbers of decimal places when the number of equations and unknowns is at all large”. Thus it has become important to prove that computers are stable enough to produce reliable linear system solutions.
So what they wanted to do was to obtain a rigorous error estimate for inverting large matrices. We had to convince the users of the computers of the credibility of its computations.
In the following excerpt, semi-diagonal is the historical wording for triangular, and “positioning for size” refers to arranging large entries for use as pivots. “High order” in the paper title means a matrix with many rows and columns.
These are the excerpts:
CHAPTER IV. THE ELIMINATION METHOD
4.1. Statement of the conventional elimination method. … The elimination method is usually viewed as one for equation-solving and not for matrix-inverting, but this actually amounts to the same thing: Given a nonsingular matrix $A = (a_{ij})$ ($i, j = 1, \ldots, n$) and the corresponding equation system
\[(4.1) \qquad \sum_{j=1}^{n} a_{ij} x_j = y_i \qquad (i = 1, \ldots, n),\]…
Given the system of $n$ equations (4.1) with the $n$ unknowns $x_1, \ldots, x_n$, the solution by elimination proceeds in the following, familiar way:
Assume that the $k-1$ first unknowns $x_1, \ldots, x_{k-1}$ ($k = 1, \ldots, n-1$) have already been eliminated, and that, for the remaining $n-k+1$ unknowns $x_k, \ldots, x_n$, $n-k+1$ equations have been derived:
\[(4.4) \qquad \sum_{j=k}^{n} a_{ij}^{(k)} x_j = y_i^{(k)} \qquad (i = k, \ldots, n).\]Then the elimination of the next unknown, $x_k$, is effected by subtracting the $a_{ik}^{(k)}/a_{kk}^{(k)}$-fold of equation number $k$ from equation number $i$ ($i = k+1, \ldots, n$). This gives a new set of equations
\[(4.5) \qquad \sum_{j=k+1}^{n} a_{ij}^{(k+1)} x_j = y_i^{(k+1)} \qquad (i = k+1, \ldots, n),\]where
\[(4.6) \qquad a_{ij}^{(k+1)} = a_{ij}^{(k)} - a_{ik}^{(k)} a_{kj}^{(k)} / a_{kk}^{(k)} \qquad (i, j = k+1, \ldots, n),\] \[(4.7) \qquad y_i^{(k+1)} = y_i^{(k)} - (a_{ik}^{(k)} / a_{kk}^{(k)}) y_k^{(k)} \qquad (i = k+1, \ldots, n).\]The transition from (4.4) to (4.5) is clearly an inductive step from $k$ to $k+1$. This induction begins, of course, with the original equations (4.1), that is, we have
\[(4.8) \qquad a_{ij}^{(1)} = a_{ij} \qquad (i, j = 1, \ldots, n),\] \[(4.9) \qquad y_i^{(1)} = y_i \qquad (i = 1, \ldots, n).\]The induction produces (4.4) successively for $k = 1, \ldots, n$, that is, it produces
\[(4.10) \qquad a_{ij}^{(k)} \qquad (k = 1, \ldots, n;\ i, j = k, \ldots, n),\] \[(4.11) \qquad y_i^{(k)} \qquad (k = 1, \ldots, n;\ i = k, \ldots, n).\]After all $n$ systems (4.4) have been derived, the first equation of each system is selected, and these are combined to a new system of $n$ equations with the $n$ original unknowns $x_1, \ldots, x_n$:
\[(4.12) \qquad \sum_{j=k}^{n} a_{kj}^{(k)} x_j = y_k^{(k)} \qquad (k = 1, \ldots, n).\]These are now solved by a backward induction over $k = n, \ldots, 1$:
\[(4.13) \qquad x_k = \frac{1}{a_{kk}^{(k)}} y_k^{(k)} - \sum_{j=k+1}^{n} \frac{a_{kj}^{(k)}}{a_{kk}^{(k)}} x_j.\]…
4.3. Statement of the elimination method in terms of factoring $A$ into semi-diagonal factors $C$, $B’$. We return now to the procedure of §4.1, without positioning for size, for the balance of this chapter.
Summing (4.7) over $k = 1, \ldots, i-1$, and remembering (4.9), gives
\[(4.15) \qquad y_i = y_i^{(i)} + \sum_{k=1}^{i-1} \frac{a_{ik}^{(k)}}{a_{kk}^{(k)}} y_k^{(k)}.\]We have $\xi = (x_i)$, $\eta = (y_i)$, let us introduce in addition $\zeta = (y_i^{(i)})$. Then (4.12) and (4.15) express two very simple matrix relations between $\xi$ and $\zeta$ and between $\eta$ and $\zeta$. If we define
\[B' = (b'_{ij}) \qquad (i, j = 1, \ldots, n)\] \[(4.16) \qquad \text{with}\quad b'_{ij} = \begin{cases} a_{ij}^{(i)} & \text{for } i \leq j \\ 0 & \text{for } i > j \end{cases}\] \[C = (c_{ij}) \qquad (i, j = 1, \ldots, n)\] \[(4.17) \qquad \text{with}\quad c_{ij} = \begin{cases} a_{ij}^{(i)} / a_{jj}^{(j)} & \text{for } i \geq j \\ \text{[hence} & \\ 1 & \text{for } i = j\text{]} \\ 0 & \text{for } i < j \end{cases}\]then (4.12), (4.15) become
\[(4.18) \qquad B'\xi = \zeta,\] \[(4.19) \qquad C\zeta = \eta.\]Since these are identities with respect to the original variables $x_1, \ldots, x_n$, that is, with respect to $\xi$, therefore comparison of (4.18), (4.19) with (4.1’) gives
\[(4.20) \qquad A = CB'.\]From (4.20)
\[(4.21) \qquad A^{-1} = B'^{-1} C^{-1},\]and (4.16), (4.17) show that $B’$, $C$ are semi-diagonal (upper and lower, that is, in \(\mathcal{C}_{+}\) and \(\mathcal{C}_{-}\) respectively). Furthermore, (4.7), (4.13), which represent the conventional way of expressing the elimination method, are clearly the inductive processes that invert (4.15), (4.12), that is, (4.19), (4.18), that is, they invert the matrices $C$, $B’$. $C$, $B’$ are semi-diagonal, and renewed inspection of (4.7), (4.13) shows at once that these are indeed the inductive processes that are required to invert semi-diagonal matrices. (In this connection cf. the remark at the end of §3.4, and the explicit expressions (4.29), (4.30).)
We may therefore interpret the elimination method as one which bases the inverting of an arbitrary matrix $A$ on the combination of two tricks: First, it decomposes $A$ into a product of two semi-diagonal matrices $C$, $B’$, according to (4.20), and consequently the inverse of $A$ obtains immediately from those of $C$, $B’$, according to (4.21).$^{27}$ Second, using the semi-diagonality of $C$, $B’$, it forms their inverses by a simple, explicit, inductive process.
$^{25}$ Or at least one which has the same order of magnitude as the maximum in question. We propose, however, to disregard this possible relaxation of the requirement. We shall postulate that \(\lvert a_{kk}^{(k)}\rvert\) be strictly equal to \(\mathrm{Max}_{i,j=k,\ldots,n}\lvert a_{ij}^{(k)}\rvert\).
$^{26}$ Positioning for size, as described above, occurs only for $k = 1, \ldots, n-1$. For $k = n$, however, $a_{kk}^{(k)}$ is the only $a_{ij}^{(k)}$, hence the assertion is trivial.
The quoted expression (4.17) is retained as transcribed. In the elimination notation used above, the multiplier for row $i$ at stage $j$ is $a_{ij}^{(j)}/a_{jj}^{(j)}$ for $i>j$, with $c_{ii}=1$ and $c_{ij}=0$ for $i<j$. This follows directly from (4.15); the superscript $(i)$ in the quoted numerator should therefore not be used as the modern multiplier formula.
In their paper, they are not using the usual $LU$ notation, but they clearly now define the decomposition where $C$ is the lower triangular, and the $B’$ being the upper triangular.
The reason of doing this is to analyse the numerical accuracy of matrix computations.
Their algebraic factorization applies beyond the SPD matrices arising from nonsingular normal equations. For a nonsingular square matrix $A$, unpivoted elimination requires every leading principal minor to be nonzero. These minors are the determinants of the upper-left $k\times k$ submatrices:
\[\Delta_k = \det (A_{1:k, 1:k})\]Writing $\Delta_0=1$, the pivots satisfy $u_{kk}=\Delta_k/\Delta_{k-1}$ when the preceding elimination steps are defined. Nonzero leading principal minors therefore ensure nonzero pivots throughout elimination. For a nonsingular $A$, a zero leading principal minor prevents an unpivoted $LU$ factorization. The nonsingularity assumption matters: a singular matrix such as $\operatorname{diag}(1,0)$ already has triangular factors despite its zero determinant.
Their purpose was to estimate rounding errors in large matrix computations. The algebraic factorization is the modern $LU$ decomposition with different notation, but the error analysis has a narrower scope: their rigorous analysis of inversion by elimination treats symmetric positive-definite matrices. It does not establish an unconditional stability guarantee for elimination on arbitrary nonsingular matrices.
The $L$ and $U$ notation
The first appearance of the term $L$ and $U$ comes from Alan Turing’s 1948 paper “Rounding-off Errors in Matrix Processes”.
Turing doesn’t explicitly use the $A = LU$ notation. Rather, he used $A = LDU$ notation, where $L$ is the lower triangle, $D$ is the diagonal elements, and $U$ is the upper triangle.
A principal minor uses the same selected indices for rows and columns; a leading principal minor uses the initial indices $1,\ldots,k$. For example, choosing index $2$ alone gives the principal minor $a_{22}$, which is not the leading $1\times1$ minor $a_{11}$. In the statement below, Turing’s “first” principal minors refer to those initial blocks.
This is his Theorem of Triangular Resolution:
Theorem of Triangular Resolution If the principal minors of the matrix $A$ are non-singular, then there is a unique unit lower triangular matrix $L$, a unique diagonal matrix $D$, with non-zero diagonal elements, and a unique unit upper triangular matrix $U$ such that $A = LDU$. Similarly, there are unique $L’$, $D’$, $U’$ such that $A = U’D’L’$.
In this paper, Turing studies rounding errors in elimination and related factorizations for general matrices, extending the discussion beyond the SPD case. The resulting bounds depend on quantities arising during the computation; the factorization theorem alone is not a stability guarantee.
When he discusses the stability of this factorization, he introduces condition numbers. In the excerpt, $N(A)$ and $M(A)$ are his measures of matrix size; the displayed $N$- and $M$-condition numbers use those historical conventions. The matrix-norm page explains the modern idea of measuring matrix size and combining it with the size of the inverse.
8. Ill-conditioned matrices and equations
…
Consider the equations
\[\left. \begin{aligned} 1\cdot4x + 0\cdot9y &= 2\cdot7 \\ -0\cdot8x + 1\cdot7y &= -1\cdot2 \end{aligned} \right\} \qquad (8.1)\]and form from them another set by adding one-hundredth of the first to the second, to give a new equation replacing the first
\[\left. \begin{aligned} -0\cdot786x + 1\cdot709y &= -1\cdot173 \\ -0\cdot800x + 1\cdot700y &= -1\cdot200 \end{aligned} \right\} \qquad (8.2)\]The set of equations (8.2) is fully equivalent to (8.1), but clearly if we attempt to solve (8.2) by numerical methods involving rounding-off errors we are almost certain to get much less accuracy than if we worked with equations (8.1). We should describe the equations (8.2) as an ill-conditioned set, or, at any rate, as ill-conditioned compared with (8.1). It is characteristic of ill-conditioned sets of equations that small percentage errors in the coefficients given may lead to large percentage errors in the solution. If we are required to solve the equations $A\mathbf{x} = \mathbf{b}$, but the coefficients used are those of $A - S$ instead of those of $A$, $S$ being a small matrix, then, to first order in $S$, the solution obtained will be $\mathbf{x}_0 + A^{-1}S\mathbf{x}_0$, where $\mathbf{x}_0$ is the correct solution. We may average the effect of this over a random population of matrices $S$, and over the coefficients in the solution and matrix, and we shall find the
\[\frac{\text{R.M.S. error of coefficients of solution}}{\text{R.M.S. coefficient of solution}} = \frac{1}{n}\, N(A)N(A^{-1})\, \frac{\text{R.M.S. error of coefficients of } A}{\text{R.M.S. coefficient of } A}.\]This equation suggests that we might take either $N(A)N(A^{-1})$ or $\frac{1}{n} N(A)N(A^{-1})$ as a measure of the degree of ill-conditioning in a matrix. We will adopt the latter and call $\frac{1}{n} N(A)N(A^{-1})$ the $N$-condition number of $A$.
We will also use $n M(A) M(A^{-1})$ as another measure of ill-conditioning and call it the $M$-condition number of $A$. There is substantial agreement between the two measures, though the $M$-number tends to be the larger, especially with diagonal or nearly diagonal matrices.
…
Turing uses condition numbers to describe how sensitive a system’s solution is to perturbations in its coefficients. His paper also derives rounding-error bounds for matrix algorithms, including elimination; it is therefore more than an introduction to conditioning.
The later 1961 paper “Error Analysis of Direct Methods of Matrix Inversion” by James Hardy Wilkinson, a mathematician at the National Physical Laboratory (NPL), develops error bounds that make the role of element growth and pivot selection explicit. Element growth measures how large intermediate entries become relative to the entries of the original matrix. Large growth can amplify rounding errors. Wilkinson’s analysis relates the computed result to an exact computation on slightly perturbed data, an approach known as backward error analysis.
This distinguishes two questions. Conditioning is a property of the mathematical problem: how much can its solution change when its inputs change slightly? Numerical stability is a property of an algorithm: can its computed solution be interpreted as the exact solution of a nearby problem? Even a small backward error can lead to a large error in the solution of an ill-conditioned system.
Consequently, the existence of $A=LU$ does not by itself guarantee numerical stability. Elimination without row exchanges can suffer large element growth, meaning intermediate matrix entries become much larger than the original entries, even when every leading principal minor is nonzero. Pivoting strategies help control growth, but their error guarantees depend on the strategy and the resulting growth. The historical development should therefore be understood as increasingly precise error analysis under stated conditions, rather than an unconditional proof that every $LU$ computation is stable.
Interactive example: follow an elimination
Choose a preset or enter a two-by-two matrix and right-hand side. Predict the multiplier before advancing each step. Try the zero-pivot preset first without pivoting, then with it; next compare the multipliers for the small-pivot preset. The experiment implements the row-pivoting and triangular-solve steps described in ALAFF.
Step through a two-variable LU solve
Practice problems
Try each problem before opening its hint or solution. The first two build hand-calculation fluency, the next two ask you to interpret or choose an approach, the next two develop logical reasoning, and the final two connect the concept to practical work. These are original exercises; the references support the mathematical concepts they use.
1. Hand calculation: factor and solve
Find unit-lower-triangular LU factors and solve $Ax=b$ for
\[A=\begin{bmatrix}3&1\\6&3\end{bmatrix},\qquad b=\begin{bmatrix}4\\9\end{bmatrix}.\]Reveal a hint
The first multiplier is 6/3. Apply it to both the matrix row and the right-hand side.
Reveal the worked solution
The multiplier is $2$:
\[L=\begin{bmatrix}1&0\\2&1\end{bmatrix},\qquad U=\begin{bmatrix}3&1\\0&1\end{bmatrix}.\]$Ly=b$ gives $y=(4,1)^T$. $Ux=y$ then gives $x_2=1$ and $x_1=1$. Verify $A(1,1)^T=(4,9)^T$.
2. Hand calculation: keep the updated multipliers
Factor the matrix below, solve it for $b=(3,8,7)^T$, and compute its determinant from $U$:
\[A=\begin{bmatrix}1&2&0\\2&5&1\\1&3&3\end{bmatrix}.\]Reveal a hint
After clearing the first column, use the updated second-column entry in the third row.
Reveal the worked solution
The first-column multipliers are $2$ and $1$. The updated lower rows are $(0,1,1)$ and $(0,1,3)$, so the next multiplier is $1$:
\[L=\begin{bmatrix}1&0&0\\2&1&0\\1&1&1\end{bmatrix},\qquad U=\begin{bmatrix}1&2&0\\0&1&1\\0&0&2\end{bmatrix}.\]Forward substitution gives $y=(3,2,2)^T$; backward substitution gives $x=(1,1,1)^T$. The determinant is $1\cdot1\cdot2=2$.
3. Thinking: a zero pivot is not the same as singularity
For
\[A=\begin{bmatrix}0&2\\1&3\end{bmatrix},\qquad b=\begin{bmatrix}4\\7\end{bmatrix},\]explain why unpivoted elimination stops, then find $P,L,U$ and solve the system.
Reveal a hint
Exchange equations and exchange the corresponding right-hand-side entries.
Reveal the worked solution
The first pivot is zero, but $\det A=-2\ne0$. Use
\[P=\begin{bmatrix}0&1\\1&0\end{bmatrix},\quad L=I,\quad U=\begin{bmatrix}1&3\\0&2\end{bmatrix}.\]$Pb=(7,4)^T$, giving $x_2=2$ and $x_1=1$. Using the original $b$ after swapping only $A$ would solve a different system.
4. Thinking: compare two pivot choices
For \(A=\begin{pmatrix}\varepsilon&1\\1&1\end{pmatrix}\) with $0<\varepsilon<1$, find the first multiplier with and without partial pivoting. Why is the pivoted multiplier preferable?
Reveal a hint
Compare the two possible first pivots: ε and 1.
Reveal the worked solution
Without pivoting, $m=1/\varepsilon$. After exchanging rows, $m=\varepsilon$ and the second pivot is $1-\varepsilon$. The pivoted multiplier avoids scaling a row by a very large number when $\varepsilon$ is small. This reduces a source of rounding-error amplification; it does not fix inherent ill-conditioning when $\varepsilon$ approaches $1$.
5. Logic: prove normalized LU uniqueness
For nonsingular $A$, suppose $A=LU=\widetilde L\widetilde U$, with both lower factors unit lower triangular and both upper factors upper triangular. Prove the factors are equal.
Reveal a hint
A matrix that is both lower and upper triangular must be diagonal.
Reveal the worked solution
All factors are invertible. Rearranging gives
\[\widetilde L^{-1}L=\widetilde U U^{-1}.\]The left side is unit lower triangular, and the right side is upper triangular. Their common value is therefore diagonal with diagonal entries $1$, hence $I$. Thus $L=\widetilde L$ and $U=\widetilde U$.
6. Logic: test a claim about singular matrices
Someone says: “If $\det A=0$, no LU factorization exists.” Give a counterexample and explain which conclusion singularity actually prevents.
Reveal a hint
A diagonal matrix is already triangular.
Reveal the worked solution
Take $A=\operatorname{diag}(1,0)$, $L=I$, and $U=A$. Then $A=LU$, despite $\det A=0$. Singularity prevents a unique solution for every right-hand side. It does not rule out triangular factors. The existence-and-uniqueness condition near the definition explicitly concerns nonsingular matrices.
7. Applied: reuse a factorization
One simulation repeatedly solves with \(A=\begin{pmatrix}2&1\\4&3\end{pmatrix}\). Solve for $b^{(1)}=(3,7)^T$ and $b^{(2)}=(1,1)^T$ using a single factorization. What work can be shared?
Reveal a hint
Use \(L=\begin{pmatrix}1&0\\2&1\end{pmatrix}\) and \(U=\begin{pmatrix}2&1\\0&1\end{pmatrix}\).
Reveal the worked solution
For the first right-hand side, $y^{(1)}=(3,1)^T$ and $x^{(1)}=(1,1)^T$. For the second, $y^{(2)}=(1,-1)^T$ and $x^{(2)}=(1,-1)^T$. Share the computation of $L,U$; each new $b$ requires its own two triangular solves. If $A$ changes, the existing factors generally cannot be reused unchanged.
8. Applied: interpret a solver check
For \(A=\begin{pmatrix}2&1\\4&3\end{pmatrix}\), $b=(3,7)^T$, and computed $\widehat x=(1.01,0.99)^T$, compute $r=b-A\widehat x$. Does a small residual always mean a small solution error?
Reveal a hint
First check the original equations. Then consider a matrix with a very small diagonal entry.
Reveal the worked solution
$A\widehat x=(3.01,7.01)^T$, so $r=(-0.01,-0.01)^T$. A residual measures the equation mismatch, not directly the error in $x$. For $A=\operatorname{diag}(1,\varepsilon)$, $b=(1,\varepsilon)^T$, and $\widehat x=(1,0)^T$, the residual is $(0,\varepsilon)^T$, arbitrarily small as $\varepsilon\to0$, while the error relative to the exact $x=(1,1)^T$ has norm $1$. Conditioning must also be considered; see LAPACK’s error discussion.
Further learning
- ALAFF: LU with partial pivoting: move from the two-variable experiment to the general algorithm and its storage layout.
- LAPACK: linear equations: see how software separates factorization, solving, and condition estimation.
- LAPACK: backward error and conditioning: develop the distinction in exercise 8 between satisfying equations and recovering an accurate solution.
Related pages
References
- Banachiewicz, T. (1938). Méthode de résolution numérique des équations linéaires, du calcul des déterminants et des inverses, et de réduction des formes quadratiques. Bulletin International de l’Académie Polonaise des Sciences et des Lettres. Classe des Sciences Mathématiques et Naturelles. Série A: Sciences Mathématiques, 393–401.
- Jensen, H. (1944). An attempt at a systematic classification of some methods for the solution of normal equations (Meddelelse No. 18). Geodætisk Institut.
- Dwyer, Paul S. “A Matrix Presentation of Least Squares and Correlation Theory with Matrix Justification of Improved Methods of Solution.” The Annals of Mathematical Statistics, vol. 15, no. 1, 1944, pp. 82–89. JSTOR, http://www.jstor.org/stable/2236214. Accessed 10 Oct. 2026.
- John von Neumann and Herman H. Goldstine, Bulletin of the American Mathematical Society, 53 (1947), pp. 1021–1099.
- Harold Hotelling “Some New Methods in Matrix Calculation,” The Annals of Mathematical Statistics, Ann. Math. Statist. 14(1), 1-34, (March, 1943)
- A. M. TURING, ROUNDING-OFF ERRORS IN MATRIX PROCESSES, The Quarterly Journal of Mechanics and Applied Mathematics, Volume 1, Issue 1, 1948, Pages 287–308, https://doi.org/10.1093/qjmam/1.1.287
-
J. H. Wilkinson. 1961. Error Analysis of Direct Methods of Matrix Inversion. J. ACM 8, 3 (July 1961), 281–330. https://doi.org/10.1145/321075.321076
- van de Geijn, R. A., and Myers, M. Advanced Linear Algebra: Foundations to Frontiers. Existence of the LU factorization and LU factorization with partial pivoting.
-
Anderson, E., et al. (1999). LAPACK Users’ Guide. Linear Equations. Triangular solves and reuse of factorizations.
-
Anderson, E., et al. (1999). LAPACK Users’ Guide. Further Details: Error Bounds for Linear Equation Solving. Residuals, backward error, and conditioning.
- OpenStax. College Algebra 2e. Solving Systems with Inverses. Identity, inverse, and nonsingularity.
- OpenStax. Intermediate Algebra 2e. Solve Systems of Equations Using Determinants. Two-by-two determinant calculations.
- Strang, G. (2011). MIT OpenCourseWare, 18.06SC. Projections onto Subspaces. Orthogonal projection and least squares.